Application · VonFlow
Everything said at this desk becomes text.
VonFlow is the voice layer of the studio's own desk. Hold a key and speak, record a call and read it back afterwards, or drop in a voice note. It all runs on the Mac it is installed on, and nothing it hears ever leaves that machine.
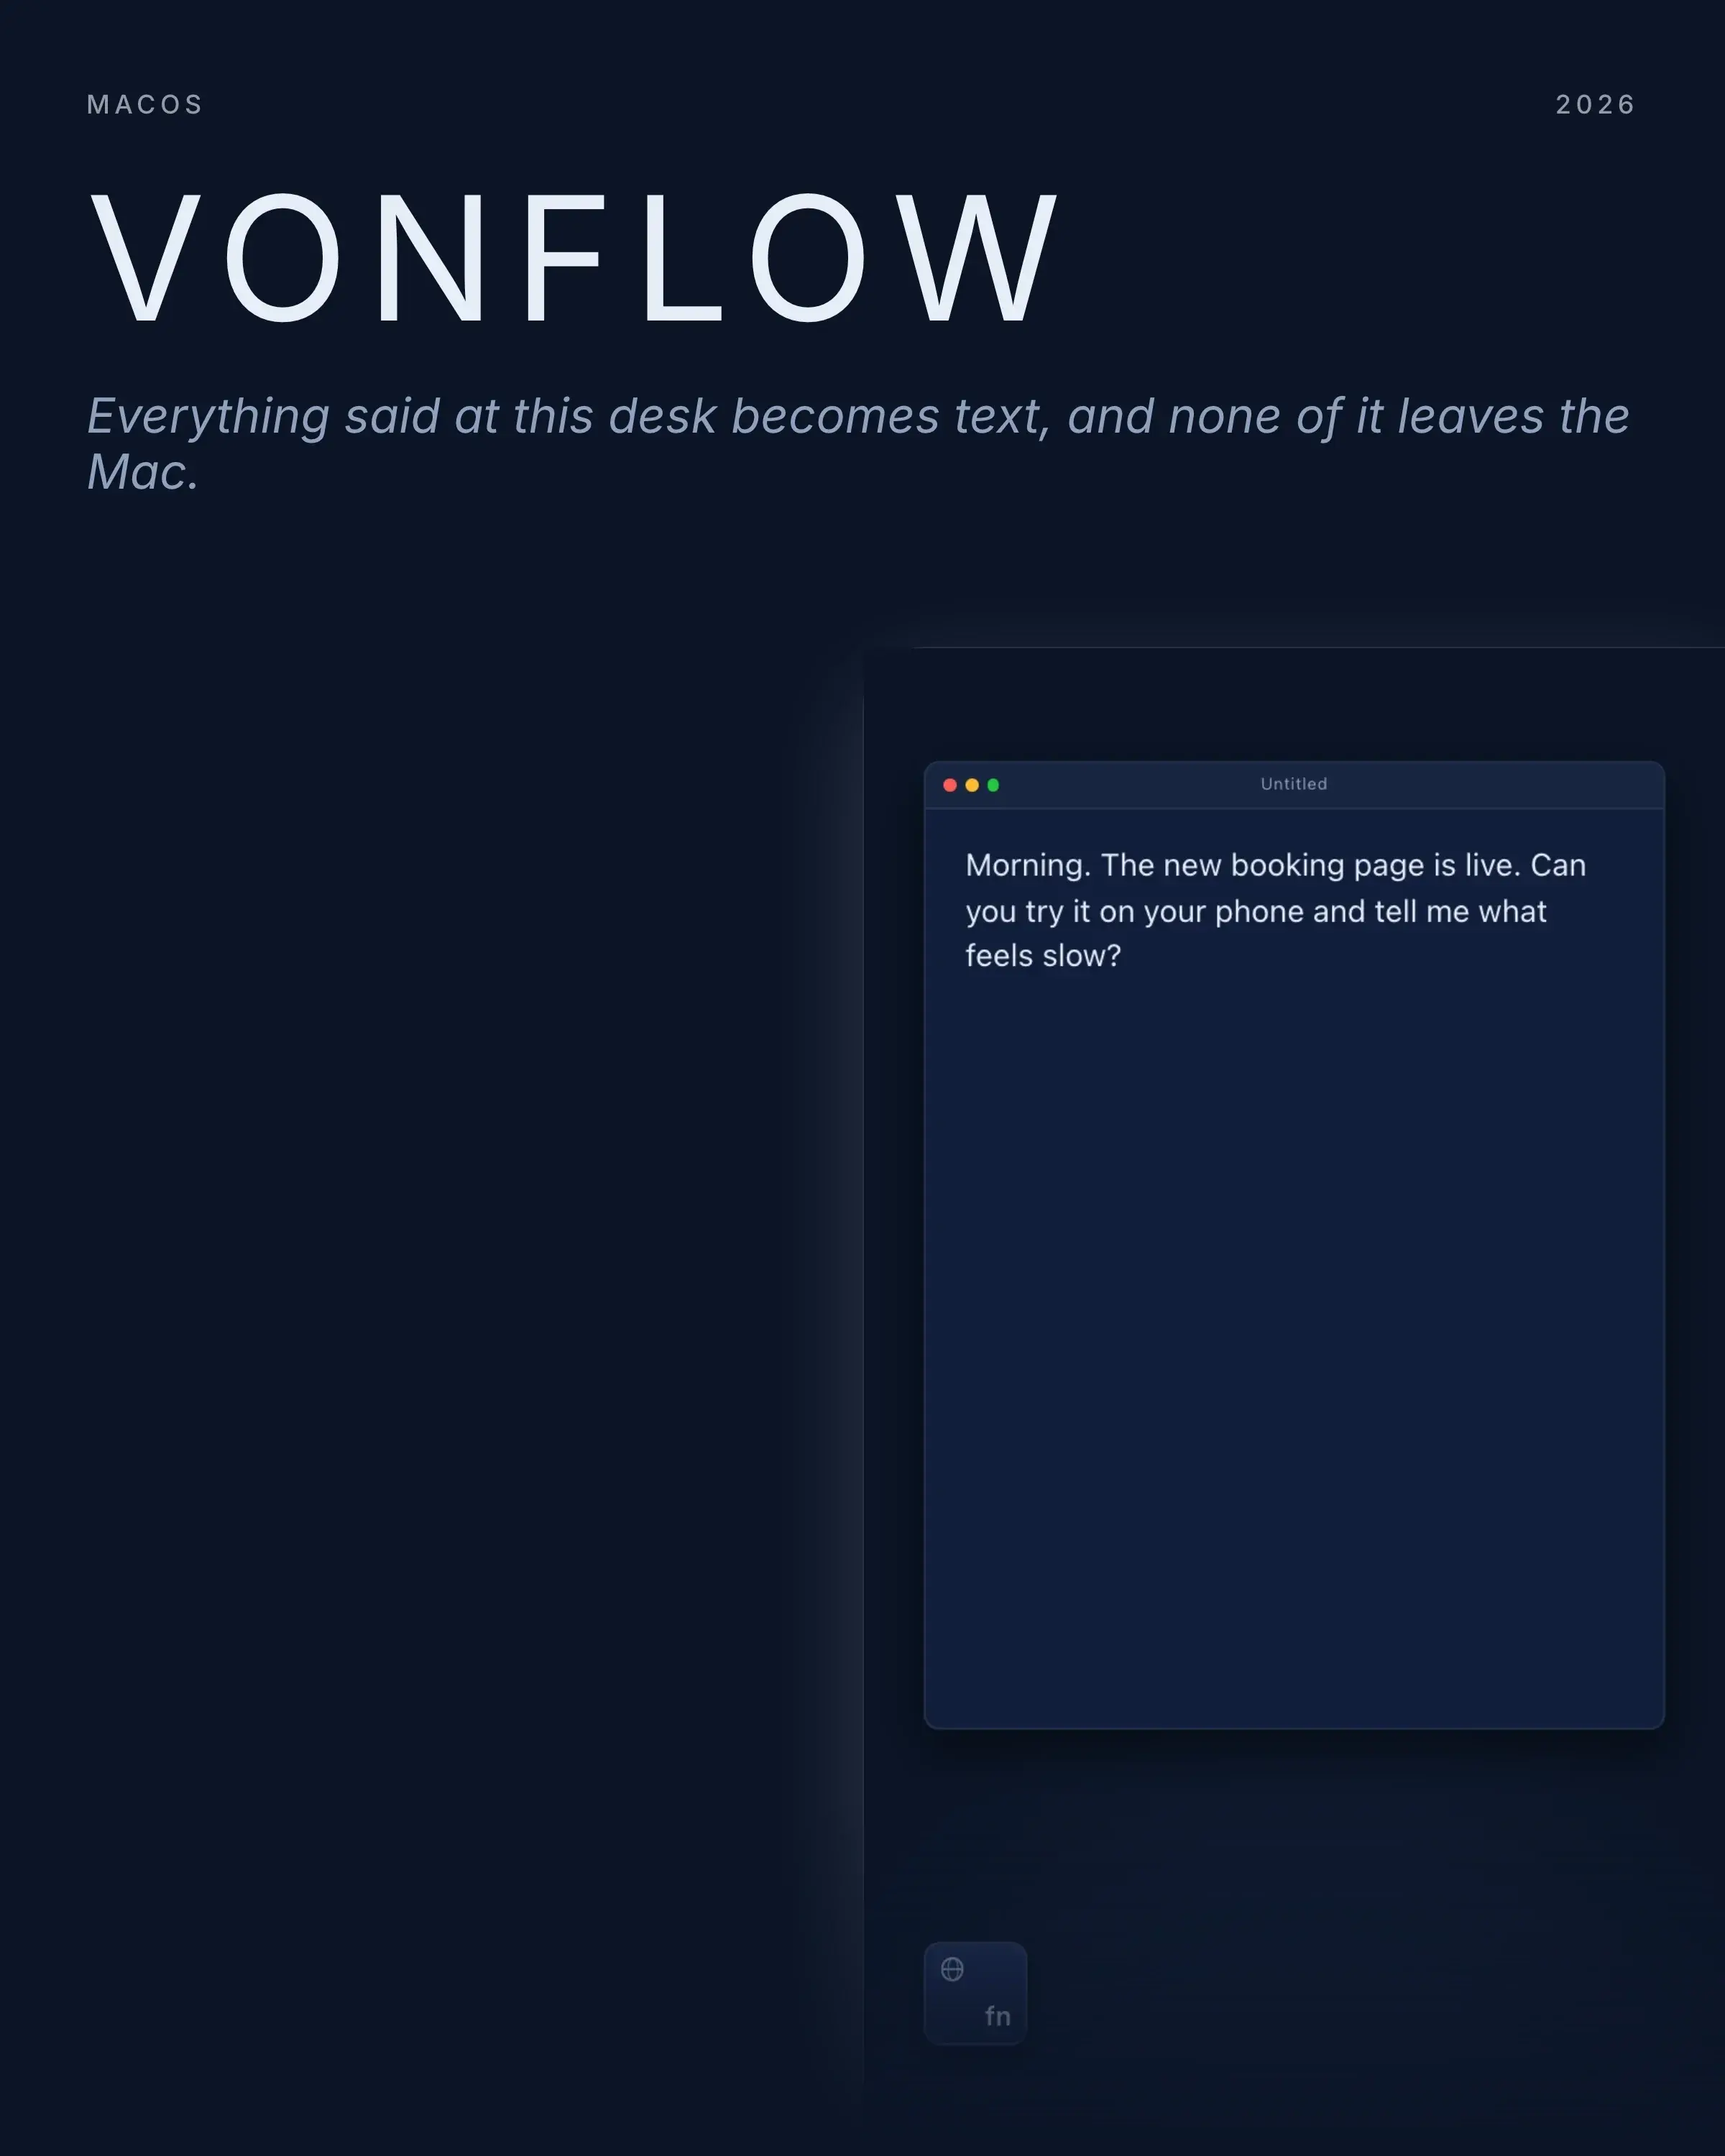
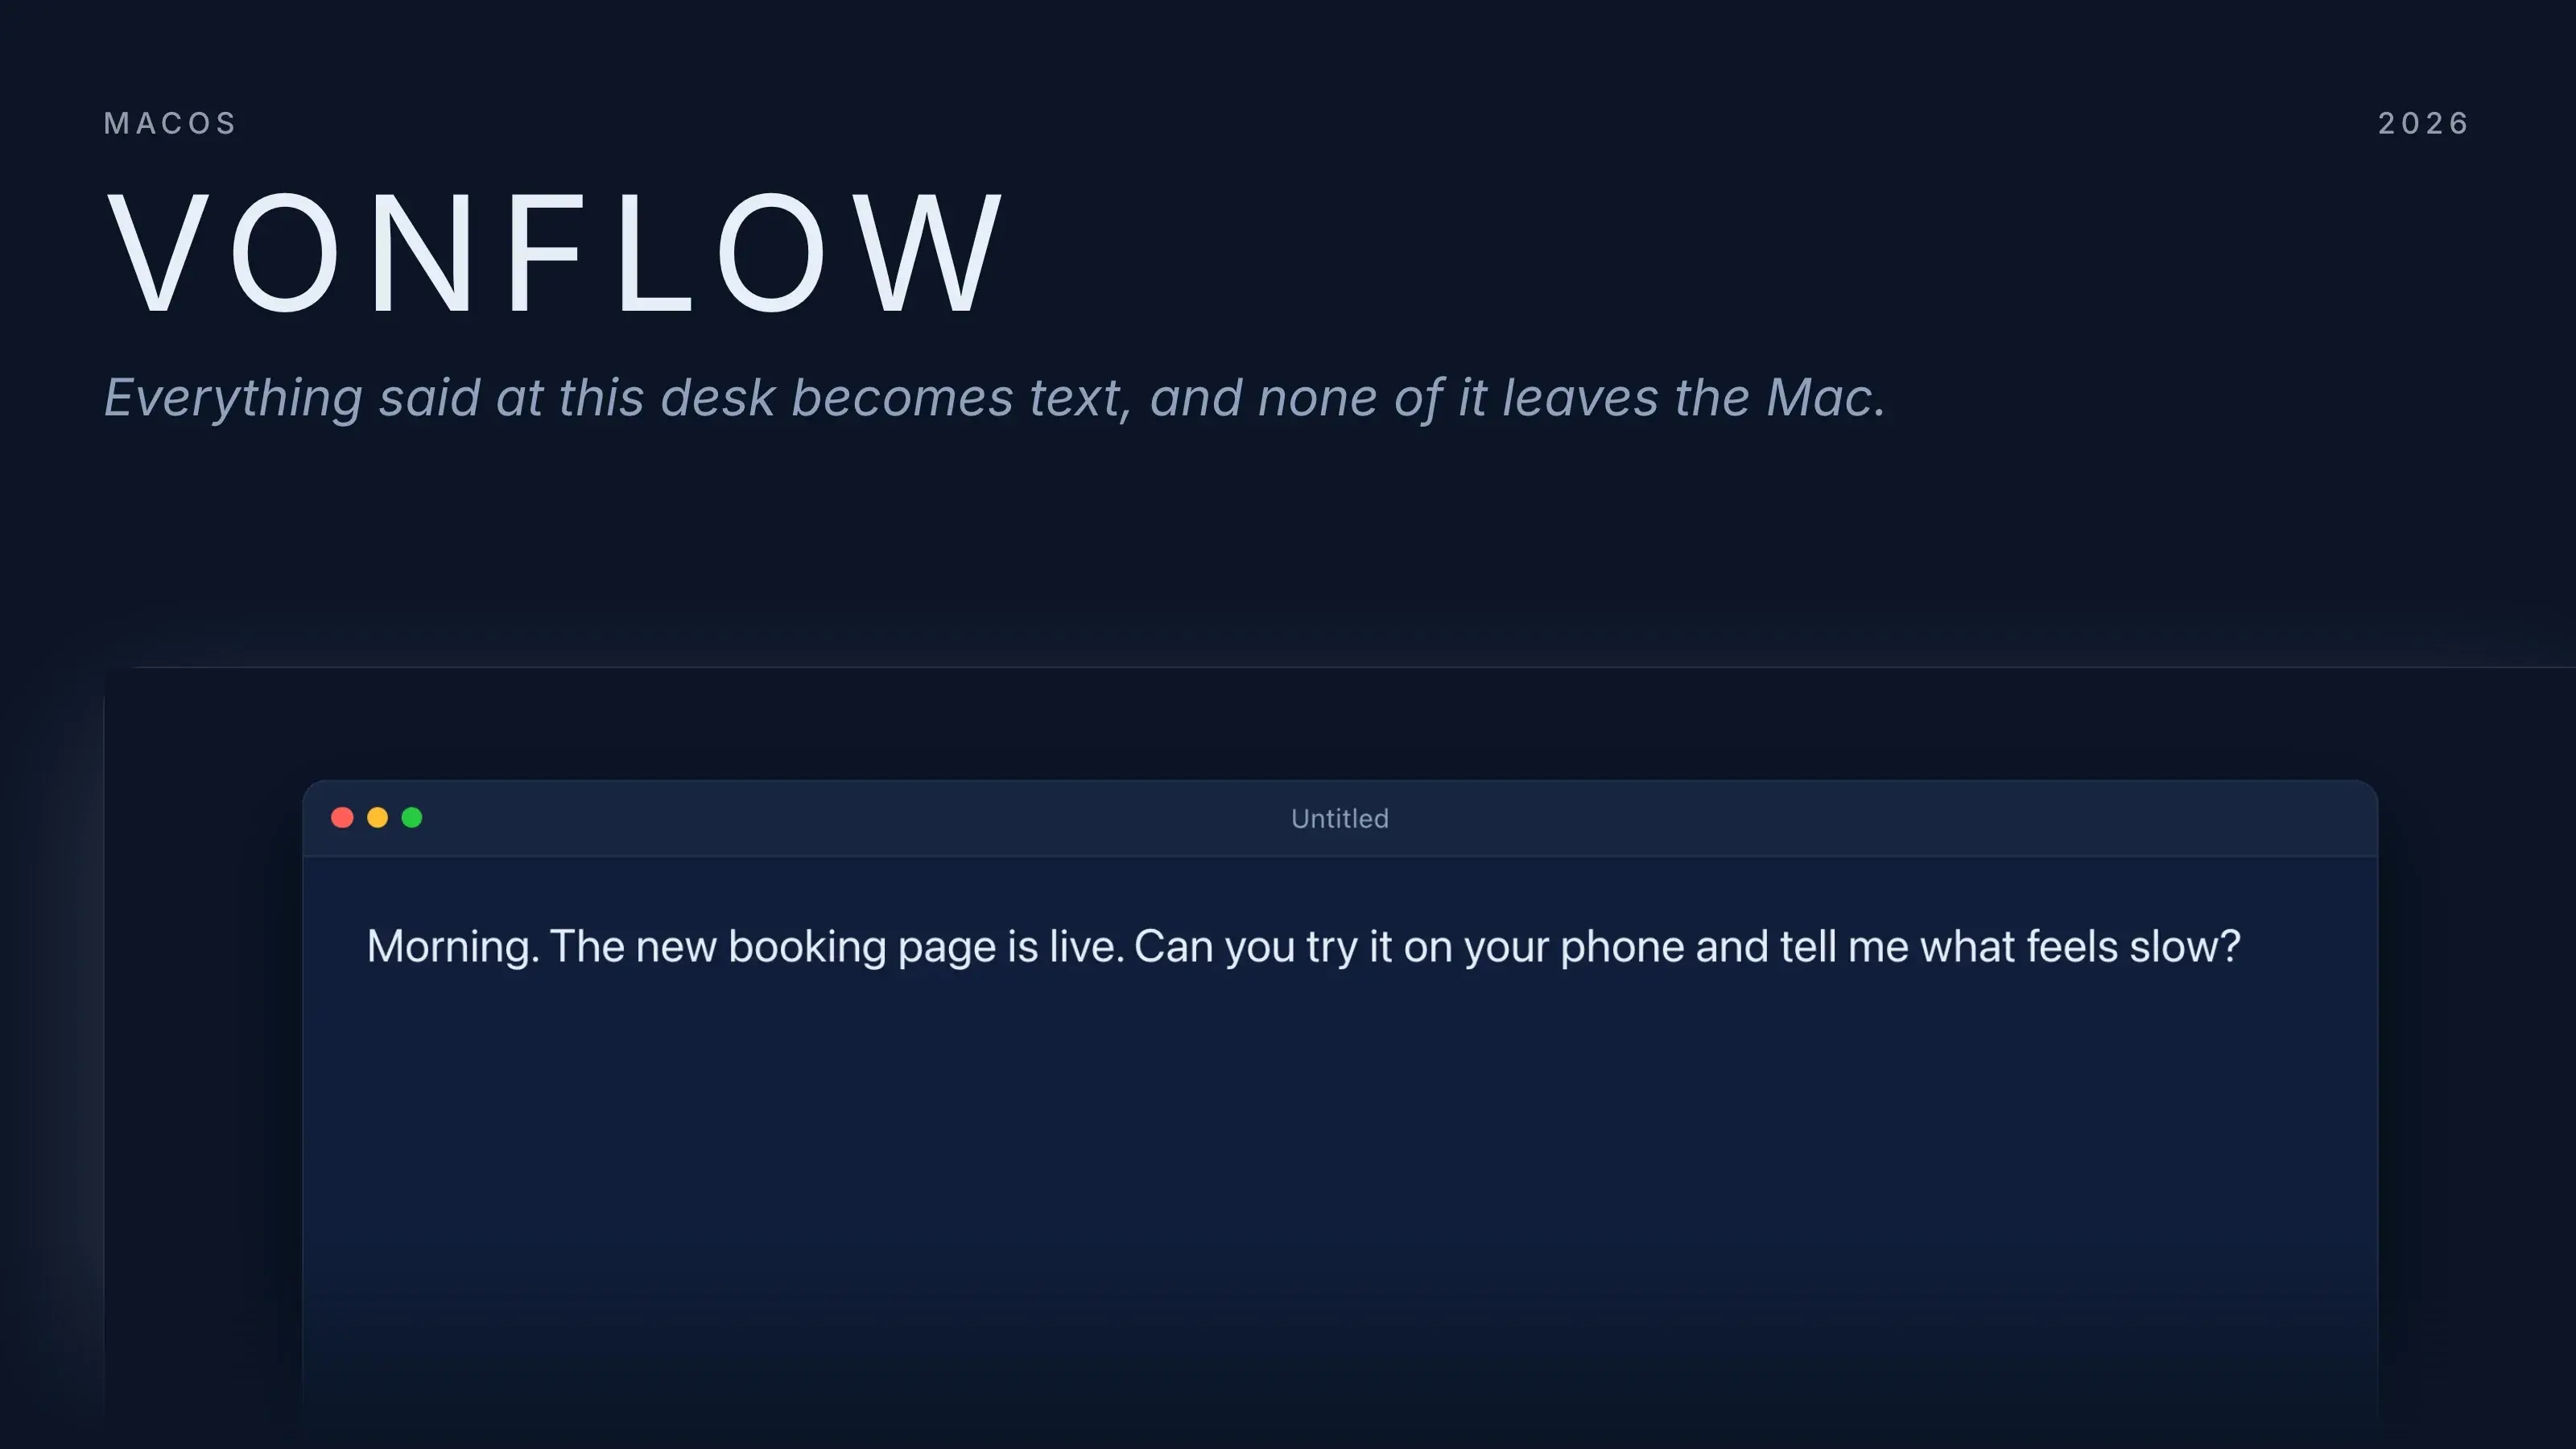
One dictation. Drawn from the application’s own interface rather than filmed: hold the key, speak, let go, and the text is placed. The bars are the mark. At rest they settle into the V; a voice pushes them out of it and silence puts them back.
What it is
Dictation on a Mac usually means one of two things: the one the operating system hands you, or a subscription that ships your voice to somebody else's servers to be written up. VonFlow is the third option. It was built here in a single day on 3 July 2026, it has been how this desk writes ever since, and every word it hears is transcribed, cleaned and inserted on the machine itself. There is no account to make, no upload, and no third party holding a copy of anything it hears. The only copy is on this Mac.
Execution
What it does
VonFlow is the voice layer of the studio's own desk. Hold a key and speak, record a call and read it back afterwards, or drop in a voice note. It all runs on the Mac it is installed on, and nothing it hears ever leaves that machine.
Who runs it
One person built it and one person keeps it running. The first commit is dated 3 July 2026 and a working app landed the same day; there have been 30 commits since. It stopped being a demonstration immediately: 437 of those 506 dictations went straight into the editor where this studio’s work gets written. Every figure on this page was read from the application’s own database, on the maker’s Mac, on 15 September 2026.
We build tooling like this for other people's desks too: See what the studio automates
The studio’s character
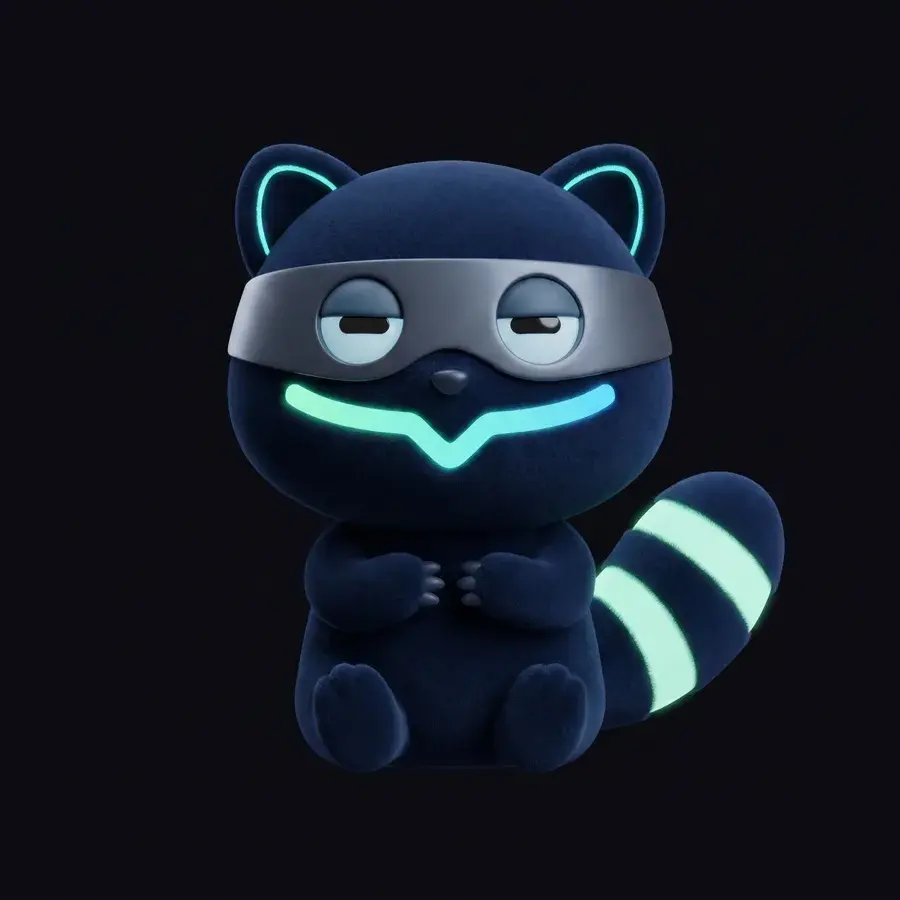
This is Vonzie.
His mouth draws the same V the waveform settles into, which is the whole reason he looks the way he does. He belongs to the studio, not to this application: VonFlow turns speech into text, and that is the entire job. He is here because a desk you can talk at is worth a picture.
The studio behind it
Built here, run here.
We build our own software for the same reason we build yours properly: because the thing that has to keep working after launch is the thing worth getting right.